The question I could not type
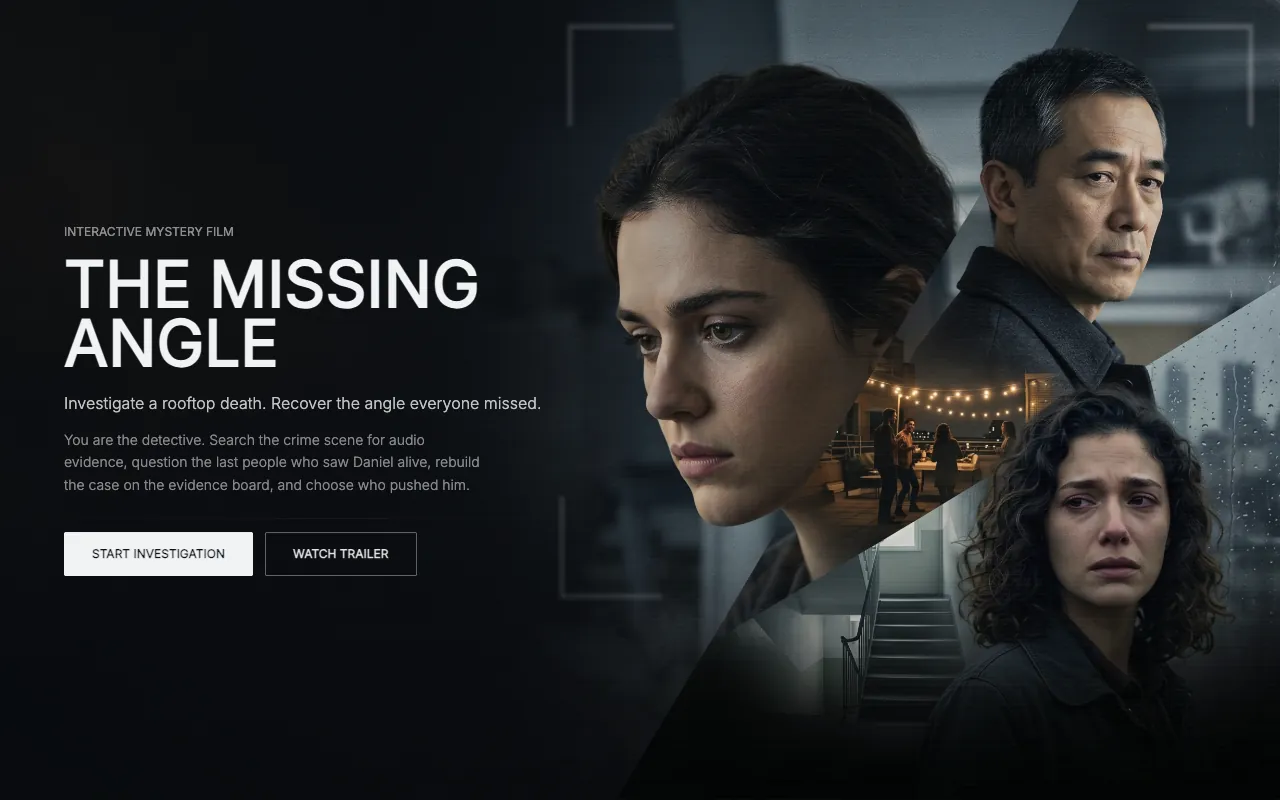
The Missing Angle is an interactive detective film that lets you interrogate three AI suspects out loud over WebRTC, search a 3D rooftop for clues, and name the killer, built by Anirudh Vasudevan for ElevenLabs Hack #10: Speech Engine.
Every mystery game I have played lets you pick a question from a list. You click "Where were you at 11pm?" and the suspect reads a line someone wrote months ago. The moment you want a follow-up the game did not expect, the illusion is over.
ElevenLabs Hack #10 was built around their Speech Engine, a service that runs the whole voice loop (microphone, speech-to-text, turn-taking, interruptions, text-to-speech) and calls your server for the words. With that handled, I could spend the weekend on suspects who lie, deflect, and crack when you push them with your own voice.
Why the suspects dial into my server
The obvious approach was to build the voice loop myself: MediaRecorder, a speech-to-text call, an LLM, a text-to-speech call, play the MP3. It works, but it is push-to-talk. You cannot interrupt a suspect, and every answer starts with seconds of silence.
The second option was to hand each character to a hosted voice agent and run no server at all. I passed on it because the suspect's brain would then live in a dashboard outside my code, and I wanted the prompts, the reply filters and the interview log in the repo where I could change them.
Speech Engine flips the direction. Instead of my browser calling ElevenLabs, ElevenLabs calls me. When a player starts a session, ElevenLabs opens a WebSocket to my server, sends transcripts as the player speaks, and expects a text stream back, which it voices. ElevenLabs owns the microphone, STT, TTS, turn-taking and barge-in. I own one transcript handler and three system prompts.
Groq's llama-3.3-70b-versatile was the brain because a nervous suspect has to answer fast. And Speech Engine needs a persistent public WebSocket, which Vercel cannot provide. That forced a Railway deploy for the full game and an HTTP-only fallback for Vercel.
What the player does
The Missing Angle runs through eleven scenes defined in scenes.json.
- A narrated opening video. Daniel Reed died on a rooftop after a party.
- The rooftop loads as a 3D Gaussian-splat scene. You drag to look, walk with WASD, press F for a flashlight, and click three glowing clues to hear recovered audio.
- A CCTV video shows the party, an argument, and two people leaving. Then the feed cuts.
- You video-call three suspects: Sara, Maya and Adrian Cole. Each call has two scripted questions, an evidence panel, and a "Start live voice" button that opens a Speech Engine session.
- An evidence whiteboard shows your clues as draggable corkboard cards with red-string connections, plus a Groq-written detective note per suspect based on what they told you.
- You name the killer, by clicking or by saying it. Three endings, and only one closes the case.
Music under every scene came from the ElevenLabs Music API.
Architecture
The Missing Angle has three layers: a no-bundler browser app, a single FastAPI process, and external APIs (Groq plus five ElevenLabs surfaces: Speech Engine, TTS, STT, the Music API and the WebRTC token endpoint). What makes it unusual is that ElevenLabs is both a client of my server and a service my server calls.
The game path and the live voice path never touch. Game events (scene_start, scene_interrogation_setup, ending) go out over /ws/game or the /api/game/* endpoints, and scripted answers come back as base64 MP3 inside those events. Live voice starts with a WebRTC token from /api/speech-engine/token, after which ElevenLabs opens its own WebSocket back to /ws/{character}, where a SpeechEngineServer streams Groq into the session.
Each row in the table is a choice I can point to in the code.
| Layer | Choice | Why |
|---|---|---|
| Live voice | ElevenLabs Speech Engine over WebRTC | Mic, STT, TTS, turn-taking and barge-in handled; I only supply text |
| Suspect brain | Groq llama-3.3-70b-versatile, streaming | Fast first token; max_tokens=120 keeps replies short |
| Scripted replies | ElevenLabs TTS eleven_turbo_v2_5, base64 MP3 in JSON | One round trip per answer, no audio streaming on the client |
| Spoken accusation | MediaRecorder to ElevenLabs STT scribe_v2 | A single utterance does not need a full-duplex session |
| Game transport | SessionSink, WebSocket or buffered HTTP | Same scene logic on Railway and Vercel |
| Story data | scenes.json hot-reloaded on mtime | Edit dialogue without restarting uvicorn |
| 3D rooftop | Three.js 0.180 plus @sparkjsdev/spark 2.1 via import map | Gaussian splats look like a real place and load from one file |
| Hosting | Railway primary, Vercel HTTP fallback | Railway runs one persistent process with range requests for video |
How it works
One scene runner, two transports
I also wanted a Vercel link, and Vercel has no WebSockets and a short function timeout. So every function that emits events takes a SessionSink, which either wraps a WebSocket or is an empty buffer. The HTTP endpoints create a fresh sink, run the same _send_scene_start, and return the buffer as one JSON batch.
Auto-advance between video scenes is where the modes differ. On a socket the server sleeps and sends the next scene. Over HTTP it hands the client a delay hint instead:
# server.py, SessionSink.schedule_auto_advance
if self.ws is not None:
    asyncio.create_task(
        _auto_advance(self, SCENES[next_scene_id], delay_sec, sid)
    )
else:
    self.auto_advance = {
        "next_scene_id": next_scene_id,
        "delay_ms": int(max(500, delay_sec * 1000)),
    }
On the client, app.js tries the WebSocket first with a 2.5 second fallback, forces HTTP mode when the hostname contains vercel.app, and runs batched messages through the same handle() router.
Serverless also means the in-memory StoryEngine can vanish between requests. So every HTTP body carries the client's current scene_id, and interrogation scenes also send an interview_log. _restore_scene and _merge_interview_log rebuild state before acting.
Letting ElevenLabs dial in
setup_speech_engines.py runs once and creates three Speech Engine resources, each with its own voice and a ws_url like wss://<public host>/ws/sara. When ElevenLabs connects, it sends a signed JWT in a request header, and the server checks it before accepting the socket:
# server.py, speech_engine_ws
auth_header = ws.headers.get("x-elevenlabs-speech-engine-authorization", "")
# ... (close with 1008 if the engine or API key is not configured)
try:
    verify_speech_engine_jwt(auth_header, ELEVENLABS_API_KEY)
except ValueError:
    await ws.close(code=1008)
    return
await ws.accept()
session = server.handle_connection(ws)
await session.run()
verify_speech_engine_jwt comes from the elevenlabs SDK and checks the token against my API key. Without it, anyone who found the URL could run my Groq budget through a fake session. One spoken question travels like this.
startSpeechEngine in detective-room.js fetches the token and calls Conversation.startSession with connectionType: "webrtc". onModeChange plays the suspect's video loop only while the mode is speaking, which is what makes the call feel like a call. onMessage captures every agent line into the interview log for the whiteboard.
A Groq brain per suspect
sara_engine.py holds one system prompt per suspect and a factory that builds the on_transcript handler. The handler takes the running transcript from ElevenLabs, maps agent to assistant, prepends the system prompt, and streams Groq straight into the session:
# sara_engine.py, make_transcript_handler
stream = await _groq().chat.completions.create(
    model="llama-3.3-70b-versatile",
    messages=messages,
    stream=True,
    max_tokens=120,
    temperature=0.92 if character == "COLE" else 0.85,
)
await session.send_response(stream)
session.send_response takes the stream directly, so the first words reach TTS before the model finishes. Cole gets temperature=0.92 against 0.85 for Sara and Maya. His system prompt tells him to be nervous underneath while trying to sound like a supervisor defending his job, and the higher setting was my way of loosening his wording to match. The code only records the number, not the reason.
Each prompt lists what the character knows, their cover story, how they behave under pressure, and hard rules. The rules do most of the work: two or three sentences, no lists, no stage directions like "sighs", and no questions back to the detective, because a suspect who asks "Why does that matter?" takes control of the scene.
Models do not always obey, so clean_spoken_reply strips markup and parentheticals, removes every sentence ending in a question mark, and trim_reply_length caps the result at three sentences and 52 words. The cleaner, minus the length cap, is mirrored as cleanSpokenReply in detective-room.js so subtitles match the logged line.
Scripted questions use the same prompts plus a private canon_hint from scenes.json, the fact the answer must contain, passed as "never quote verbatim" knowledge so the wording varies and the fact does not.
Hearing an accusation and picking a branch
The final choice can be spoken. app.js records with MediaRecorder and posts the blob to /api/game/voice or sends raw bytes over the socket. The server transcribes it with ElevenLabs scribe_v2.
Mapping free speech to one of three branches is a two-tier matcher. First _match_branch_key_with_groq sends the options and the transcript to a "choice director" prompt in JSON mode at temperature 0.1, and only accepts the answer above a confidence floor:
# server.py, _match_branch_key_with_groq
data = json.loads(response.choices[0].message.content)
choice_key = data.get("choice_key")
confidence = float(data.get("confidence") or 0)
if choice_key in branches and confidence >= 0.55:
    return choice_key
If that fails, _match_branch_key does it by hand: ordinal words first ("the second one"), then token overlap and SequenceMatcher ratio after stripping stopwords, with a 0.38 floor. Then a negation guard: _is_negated checks the spoken tokens against a set of eight words (not, dont, cant, cannot, wont, doubt, reject, blame), and if the speech contains one and the candidate label does not, the score is capped at 0.25. "I don't think it was Sara" should not accuse Sara.
Grounding the whiteboard in what was said
At the whiteboard scene, _build_whiteboard_brief calls _groq_witness_insights, which collects the last eight recorded replies per suspect (scripted answers and live lines captured by onMessage) and asks Groq, in JSON mode, for one detective-note sentence per witness based only on those lines. If a suspect was never interviewed, _groq_witness_insights puts that suspect's canon hints into the prompt instead. If the Groq call fails, the note becomes the suspect's last reply, or a fixed line from _default_whiteboard_brief when there are no replies at all. _build_whiteboard_brief itself only fills any empty slot with that same default.
The hard parts
Vercel's 10 second limit shaped more code than I expected. The decision scene needs three TTS clips. Over a socket the server sends the narration first and fills in the question audio from a background task; over HTTP a separate branch runs all three TTS calls through asyncio.gather so the whole scene fits in the window. The sink abstraction was supposed to hide the transport, and latency leaks through.
Model output hygiene took longer than the voice integration. The prompt rules exist because the model kept adding stage directions and ending replies with a question. The fix was rules plus regex, written twice and kept in sync by hand. On the live path the SDK voices the raw stream, so the cleaner only touches what gets logged.
Some things are plainly hacky. _handle_dr_interrogate_ws has a leftover branch that checks 'incident' in locals(). The question field is named cole_asks for every suspect and I never renamed it. There are no tests. The rooftop is a 29 MB .spz file served from the FastAPI process, slow on Vercel.
What shipped
The Missing Angle was my entry to ElevenLabs Hack #10: Speech Engine. The repo holds the full game, eight generated music beds and a trailer. No placement or award is recorded for the entry.
At the time of writing the Vercel deployment loads, but its /api/health returns 503 with GROQ_API_KEY missing, so scripted suspect answers and whiteboard notes do not run there either. It is a shell of the HTTP mode until it is redeployed with keys, and the Railway deployment that live voice needs is not running. The health endpoint exposes playable and live_voice flags and no secret values.
What I would do differently
Persist session state in Redis or a KV store and drop the client-side echo. StoryEngine is a dict in one process, which a second Railway replica would break. Pin @11labs/client to a version instead of @latest. Write tests for clean_spoken_reply and _match_branch_key, both pure functions with obvious edge cases.
The bigger change is to use Speech Engine for the accusation too, instead of a record-and-upload round trip with its own STT call and matcher. One session for the whole second half would feel better.
Key takeaways
- When a voice platform can call your server instead of the other way around, your code shrinks to a transcript handler and a system prompt.
- A sink abstraction lets one game loop run over WebSockets and buffered HTTP; keep the one transport-specific decision in a single method.
- On serverless, echo the minimal state you need (current scene, recent transcript) in every request as insurance against a cold start.
- Verify the signed header before
ws.accept()on any callback endpoint; a public WebSocket that runs an LLM on every message is a bill waiting to happen. - Treat LLM output bound for TTS as untrusted text. Strip stage directions and counter-questions in code, cap length, and mirror the cleaner on the client.
- Gate an LLM classifier with a confidence threshold and keep a deterministic fallback with a negation guard for when the model is confident and wrong.
FAQ
How does The Missing Angle use ElevenLabs Speech Engine?
The Missing Angle registers one Speech Engine resource per suspect, each with a ws_url pointing at a FastAPI endpoint such as /ws/sara. The browser starts a WebRTC session, ElevenLabs opens a WebSocket to the server with the player's transcript, and the server streams a Groq reply back for ElevenLabs to voice. Speech Engine handles the microphone, speech-to-text, turn-taking and interruptions.
Can The Missing Angle run on Vercel without WebSockets?
Yes, in a reduced mode. The Missing Angle wraps every outbound game event in a SessionSink that either writes to a WebSocket or buffers into a JSON batch. On Vercel the client calls /api/game/* over HTTP, receives batched events, and handles auto-advance with a server-supplied delay_ms hint. Each request carries the current scene_id so a cold-started function can rebuild state. Live Speech Engine interviews need a persistent WebSocket, so they do not run on Vercel.
How does The Missing Angle keep AI suspect replies short?
The Missing Angle uses two layers. The Groq system prompts demand two to three sentences, no lists, no stage directions and no questions back to the detective, with max_tokens at 120. Then clean_spoken_reply in sara_engine.py strips markup and drops any sentence ending in a question mark, and trim_reply_length caps the result at three sentences and 52 words.
Links
- Vercel deployment (currently degraded; health reports missing GROQ key): https://the-missing-angle.vercel.app
- Source: https://github.com/anirxdh/The-missing-angle
- Hackathon: ElevenLabs Hack #10: Speech Engine, https://hacks.elevenlabs.io/hackathons/9